Showing posts with label schema. Show all posts

Tuesday, November 28, 2017

1/3 of top sites uses schema on homepage


How many of the top sites on the web use: Jquery, Schema tags, Google's "nositesearchbox" to exclude the site from sitesearches on Google?

34039 urls tested from the 'top internet sites homepages' list, merging Majestic, Alexa, Statvoo, OpenDNS and Quantcast top million sites. Checking only the http://www homepage of all domains in this list.

24407 - pages have jquery in the source code (72%)
12187 - are using schema in one form or another (36%)
114 - sites had a 'nositesearchbox'  (0.3%)

The percentage of sites in the top list and the sites with nosearchbox were the items I was particularly interested in, the jquery info is a nice added bonus.

----------------

The script crawls urls in a file, stores it in a variable,  and then tests if any of the three terms given appears in the variable, counts it and lists it in a file:
(only parts shown)
while read -r line; do
acount=111; bcount=111; ccount=111
feedback=$(curl -L -s -m "$time_out" -b cookies -c cookies -A "$agent"  "$line")
if [[ $feedback ]] ; then
acount=$(echo "$feedback" | grep -i -c "$3")
bcount=$(echo "$feedback" | grep -i -c "$4")
ccount=$(echo "$feedback" | grep -i -c "$5")
fi
[[ $acount -gt 0 ]] && [[ $acount -ne 111 ]] && acounter=$(( $acounter+1))
[[ $bcount -gt 0 ]] && [[ $bcount -ne 111 ]] && bcounter=$(( $bcounter+1))
[[ $ccount -gt 0 ]] && [[ $ccount -ne 111 ]] && ccounter=$(( $ccounter+1))
echo -e "$line\t$acount\t$bcount\t$ccount" | tee -a $outfile

Tuesday, February 16, 2016

site search box in SERP


Many of us site managers and tech Seo will have thought about using the sitesearch link box in Google results. When Google displays expanded results with sub-results, they offer to integrate a sitesearch box. Posts on this are rare, and have little info on the impact of these. What I have seen so far indicates that there's no significant impact on natural search traffic. Information about on site conversion (closer match should increase on-site conversion) is not published to my knowledge, and would be hard to separate out from the overall search.

There are three options to deal with this Google offer:
1. ignore, do nothing
2. block the searchbox actively
3. integrate schema into the homepage of the site to 'invite' Google to add the box.

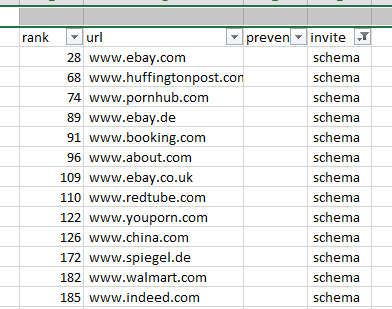
Which route to go? A first step, as often, is to look at how common it is to use one of these options. Working on one of the largest websites, I compare here with the top 10,000 sites by traffic as estimated by Alexa (top million sites report).

Now showing:

  1. how many block, use schema, do nothing,
  2. average rank of blocked sites compared to sites with schema
  3. what do the top sites do (surprise)
  4. top sites blocked by rank
  5. top sites with schema by rank 
  6. bash script to test


1. How many block, use schema, do nothing


2. Average rank of blocked sites compared to sites with schema


3. What do the top sites do (surprise)

4. Top sites blocked by rank

5. Top sites with schema by rank 

6. Bash script to test


while read -r line; do
if [[ $line != www* ]]; then
line="www.${line}"
fi
output=$(curl -s "${line}" )
nobox=$(echo "$output" | grep "nosite")
boxschema=$( echo "$output" | grep "SearchAction")

if [[ $nobox != "" ]] ; then
nobox="blocked"
fi

if [[ $boxschema != "" ]] ; then
boxschema="schema"
fi

echo -e "$line \t $nobox \t $boxschema" | tee -a nobox-or-box.txt


done < $1


Tuesday, November 11, 2014

Alexa top 10,000 and rel publisher, opengraph tags, and schema

Alexa.com might not be high in their own rankings, but they provide a very, very handy list frequently - the top 1 million domains by estimated traffic rank.

The accuracy of this data is beyond my knowledge - only Alexa has detailed insight - but I would think that this list is at least directionally right and rare in the way it is offered (Quantcast offers something similar). Thanks Alexa!

I wondered how widely used tags are, we (at SEO for Dell) consider important or at least interesting.
I wrote two small scripts to test for the implementation and also to calculate or count, and here are the results.

Tested for 3 elements:

  1. og:title - checking for the implementation of anything related to opengraph.org tags
  2. rel_publisher - if the tag is implemented on the homepage, as recommended by Google
  3. schema - this tests for implementation anything related to schema.org, according to the search engine recommendations.

All items are only tested on the homepage of the 10,000 domains! And if a domain did not answer - some are not set up properly and do not forward to a default subdomain like www - all values are set to 'no' by default. I manually checked the first 400 urls, and this happened twice.

First observation - these tags are FAR from everywhere. 

Opengraph is on ~ 26% of homepages, rel publisher on 17% and schema only on 10%.
(First column = line counts)


Second observation is interesting, but seems a relatively weak correlation:

The implementation of opengraph,  rel publisher and schema happens slightly more often on the higher ranking homepages. This is most pronounced for schema, least for opengraph, which has the highest overall adoption rate.


Is this compelling you to implement on your site?

Wednesday, October 29, 2014

Script to check for Opengraph tags, schema and rel publisher


How common are tags like opengraph, schema and rel publisher?

These are interesting, perhaps important features of a website, not just, but also for seo. What better than to take a look at a larger number of sites, and to check if they use these tags.
This is the output of a little script to test for these three tags (schema.org, opengraph.org, rel_publisher for G+ ) on a list of urls.


First generate a unique filename, then copy the header into it. The while loop iterates over a list of urls, and pulls the data into a variable, because the script needs to check for several items, and this avoids to send three requests. I added the timeout parameters to wget, because several domains I tested did not send ANY response when missing the subdomain, and the script hung up.

Next steps are the three filters for og:title, rel publisher and schema (itemtype), into variables, then writing to the line with the url. Done.

#!bash
filename=topresults-$RANDOM.txt
echo -e '\turl\tog:title\trel_publisher\tschema' > ${filename}

while read -r line; do
file=$(wget -qO- -t 1 -T 10 --dns-timeout=10 --connect-timeout=10 --read-timeout=10 "${line}")

title=$(echo "${file}" | grep 'og:title'  | wc -l)
        if (( "$title" > 0 ))
                then title="yes"
        else 
                title="no"
        fi

publisher=$( echo "$file" | grep 'rel="publisher"' | wc -l )
        if (( "$publisher" > 0 ))
                then publisher="yes"
        else 
                publisher="no"
        fi

schema=$( echo "$file" | grep 'itemtype="' | wc -l )
        if (( "$schema" > 0 ))
                then schema="yes"
        else 
                schema="no"
        fi

echo -e "$line\t$title\t$publisher\t$schema" >> ${filename}

done < $1

wc -l $filename


Bookmark and Share